Building a University Website Is Easy. Building One That Works Like Software Is Different.
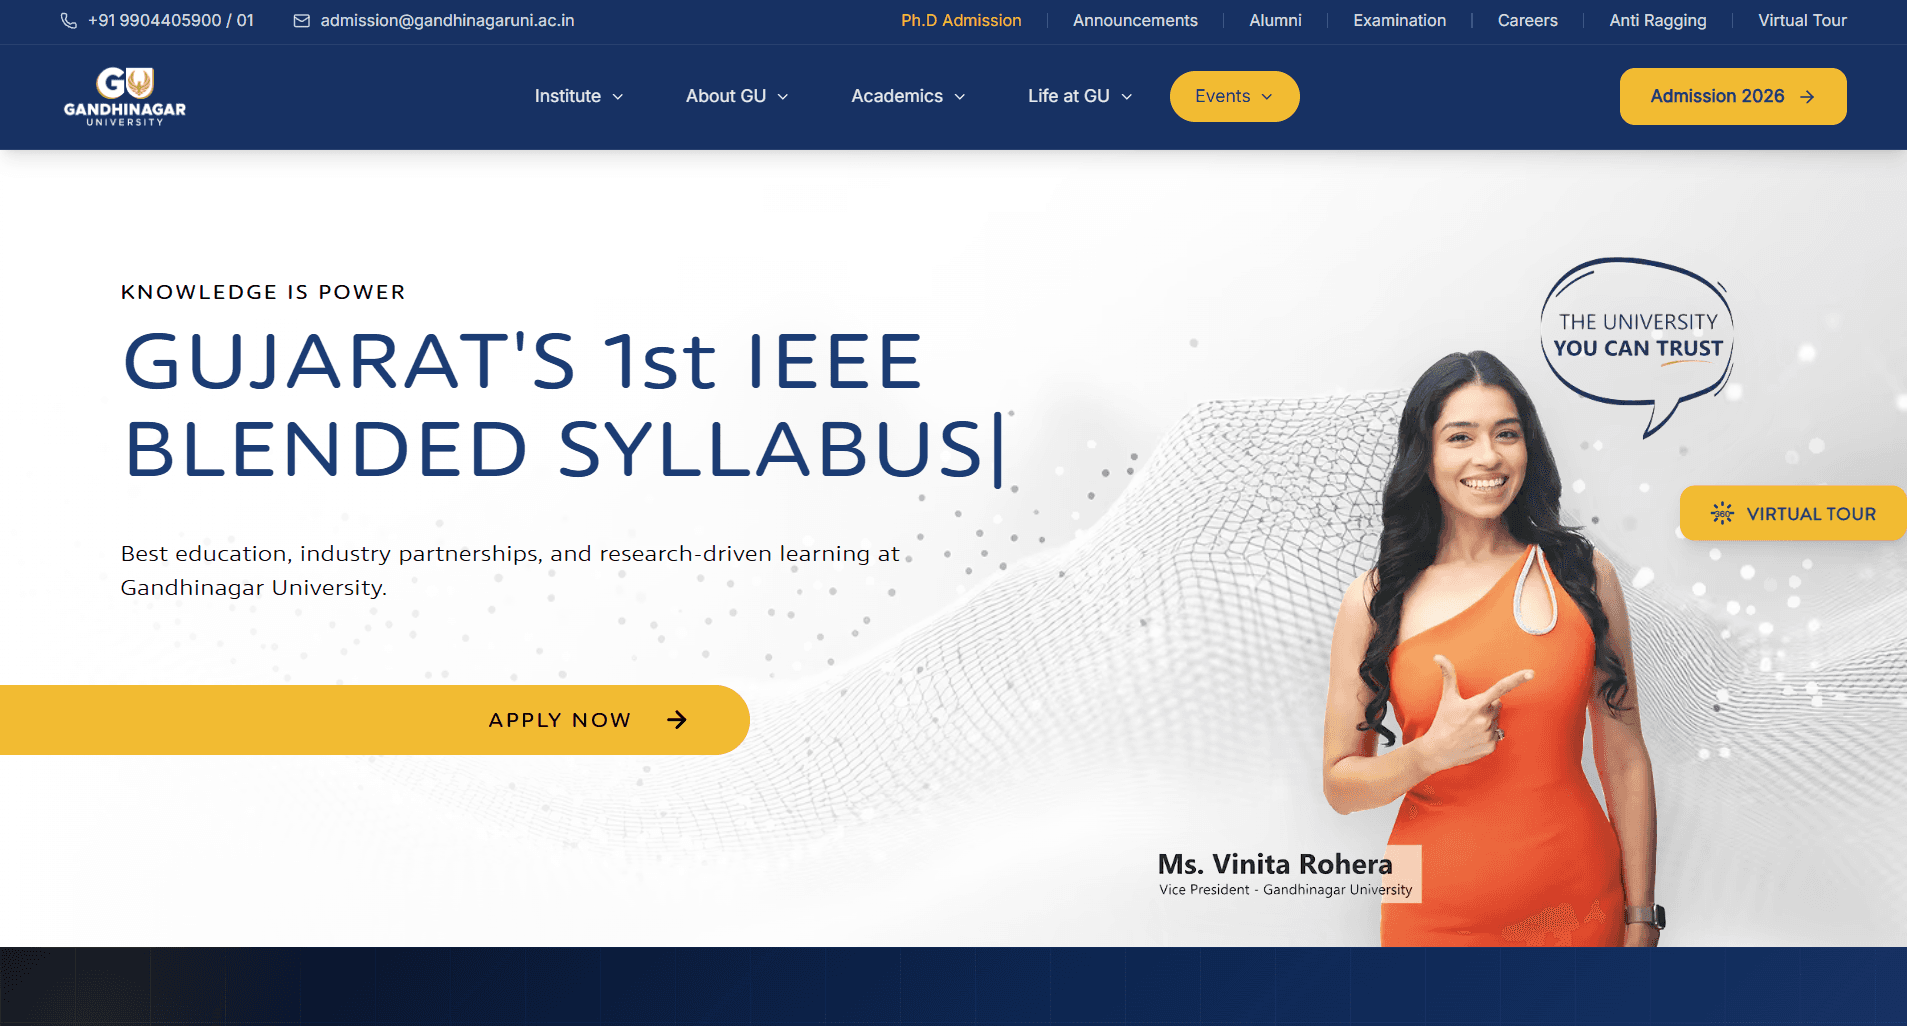
Making a landing page is easy these days. You can open an AI tool, describe what you want, generate a decent-looking website, connect a few buttons, and you have something that looks like an MVP. And honestly, there is nothing wrong with that—I have done it too.
But the interesting part starts when a website isn't just something you build, deploy, and forget.
What happens when the website has to actually be used by thousands of people every day? What happens when there are 16 distinct institutes under one roof—each with different pages, content, and designs—backed by an administrative team editing content live?
That was the kind of project Gandhinagar University became for me.
Through a friend, I got the opportunity to work on the university website with a team of five people. It was a paid client project, and for me, it was a completely different experience from building another personal side project or tutorial MVP just to learn something. I was working as a Full Stack Developer and took the lead on the frontend architecture, code structure, and overall organization of the application.
It Wasn't Just a Website
At first glance, you might think a university website is pretty straightforward: Home, About, Courses, Contact, and maybe an admin panel.
But this wasn't that.
We were building for around 16 different university institute pages—GIT (Technology), GIM (Management), GIL (Law), and others—along with the main university portal and specialized student pages.
We also didn't want to compromise on design. Our Figma designer did a really good job creating distinct visual experiences for the different institutes, and our job was to turn those designs into a maintainable, high-performance application.
Since our stack was React + Vite, reusable components became a big part of our solution. Buttons, form inputs, cards, section layouts, modal dialogs, and navigation elements—wherever the design had repetition, we built it once cleanly and reused it instead of writing duplicate code across the project.
From Static JSON to a Real Content System
Then came a problem I didn't initially expect: "Okay, but who is going to edit all this content?"
Having 16 different institute pages is one challenge. Having every piece of text, notice, and course detail editable from an admin panel without breaking the site is another.
Initially, we were keeping some of the page content separately in static JSON files. It worked for getting things started, but as the scope grew, it became clear that hardcoded JSON wasn't going to be the final solution.
So we slowly moved all that content into proper database APIs. The initial data was seeded, and eventually the frontend stopped relying on static JSON files altogether. Content started coming dynamically through APIs, and we built the CRUD side around it so the admin team could actually manage the content live.
That transition was one of the most interesting parts of the project for me because it shifted the way I thought about the website. It wasn't just a collection of pages anymore—it was becoming a software system.
Solving Codebase Structure: Monorepo with pnpm
With a project this size, one obvious approach would be to create separate repositories for everything.
But then you start sharing things: TypeScript types, API validation rules, UI components, buttons, inputs, modals, and utilities. Suddenly you're maintaining shared packages, publishing private npm packages, dealing with version mismatches, and wondering why changing one shared component became a massive task by itself.
So we decided to go with a monorepo.
For this project, I chose pnpm. I had mostly used npm in my previous client and personal projects, so pnpm wasn't completely unfamiliar, but it was the first time I was choosing it for an architecture like this. Since the repository had multiple packages, pnpm's workspace support and shared dependency store felt like a much better fit. I wanted to keep dependency management simpler, avoid unnecessary package duplication, and ensure our setup remained manageable as the monorepo grew.
One Application. 16 Institute Websites.
With 16 institutes, we could have easily created 16 separate React applications. But then imagine fixing a bug in the global navbar. You fix it once, and now you have to coordinate building and deploying that same change across 16 applications. That didn't feel right.
Instead, we built one React application that could understand which institute the visitor was coming from dynamically at runtime.
So git.gandhinagaruni.ac.in could load the GIT experience, while another institute's subdomain could load its own branding, layout, and content.
The basic concept was simple:
We used wildcard DNS and a reverse proxy to send different subdomains toward the same application. Inside React, the active hostname was resolved at runtime and matched against our predefined configuration.
That meant we could deliver distinct institute experiences without maintaining completely separate frontend apps. A shared component could be improved once and used everywhere, a global navigation change could go through a single release, and institute-specific code could be lazy-loaded so visitors only download what they actually need.
Real Problems Started After Launch
Building everything on localhost is one thing. The real problems started when people actually started using the website. We ran into a few production issues that I honestly wouldn't have thought about if I was just building another personal project.
1. The Media Upload Memory Blowout
Our server was reading these large files directly into RAM memory before sending them to storage. Under concurrent uploads, this caused sudden memory spikes and crashed the Node.js process.
So we changed the upload flow. Instead of keeping the entire file buffer in memory, we moved to temporary disk storage and processed images before storing them. We used Sharp to resize and compress images into modern formats like WebP and AVIF, while stripping out unnecessary EXIF data. It made a noticeable difference for both server stability and site loading speeds.
2. Google Sheets API Rate Limits
The admissions team wanted new prospective student leads synced to a Google Sheet in real time.
The initial version was simple: student submits form → backend → Google Sheets API. It worked perfectly with a few test submissions. But when an admission campaign hit, submissions surged simultaneously. Google's API rate limits hit us immediately, dropping requests.
Instead of calling Google Sheets synchronously, we changed the flow so that form submissions were saved directly into PostgreSQL first (<50ms response to the user). A background worker then picked up pending database records and sent them to Google Sheets in batches. The user didn't have to wait for Google Sheets to respond, and the system became much more reliable.
3. Adding an AI Chatbot (Google Gemini API)
We also added a chatbot to the website using the Google Gemini API. We didn't want a generic chatbot floating on the screen; we wanted it to actually be helpful for students.
We connected it with the university's FAQ database and administrative guidelines so it could accurately answer student inquiries. We also designed the flow so it could collect basic lead information when prospective students asked about admissions. We added rate limiting and security checks around the endpoint to ensure the chatbot couldn't be abused or drain API quotas.
Learning Docker, Postgres, and Production Tooling
This project was also a huge learning curve for backend and deployment workflows.
Docker was completely new to me. At first, I was honestly afraid of it because I didn't know what it actually did or how containerization worked. But after taking the time to read through it, understand the concepts, and get hands-on experience setting up containers, I got comfortable and properly started using Docker for deployments.
We also ran PostgreSQL in production and handled schema adjustments as features grew. For our ORM, we used Prisma—and to be completely honest, I didn't like Prisma all that much and had my share of gripes with it, but I can see how it can be useful for certain project setups. The biggest gain was learning how to write modular, clean code without duplication, making sure our backend logic remained clean and scalable.
What I Actually Took Away
The interesting thing about a large project isn't necessarily writing the most complicated code. Sometimes it's making decisions early on that stop the codebase from becoming complicated six months down the line.
At the beginning, you can always hardcode something, duplicate a component, create another repository, or put data in a JSON file saying "we'll fix it later." But eventually, as the project grows, those quick hacks come back to haunt you.
Today, the Gandhinagar University platform handles 2,000+ daily visitors smoothly. Seeing code our team architected serve thousands of students and faculty members every single day is something I'm really proud of.
This project was a major turning point for me. It gave me the confidence to move beyond simple personal projects and MVPs to architecting resilient, production-ready software systems. Building a website is one thing. Building a website that behaves like software is a completely different problem.
// Related Case Study
Explore the companion architectural case study with technical specs, impact summary, and live platform link.
Explore the Gandhinagar University project case study→Did you find this post helpful?
Written by Jaimin Kapadiya
Software Engineer & Product Builder